Watercolor: a half-built tower wrapped in wooden construction scaffolding, warm light glowing from the unfinished floors, a slender crane silhouette beside it

Day 0 | L3 Kickoff: A Short History of Harnesses, From Your Batch Script to Pi and DeepSeek Harness

Previous post: Day 16: L2 Complete! Next Stop: Harness Engineering Evolution and the L3 Blueprint. Make sure you have understood or mastered the skills Day 16 covered, and let’s start L3 from here. This is the L3 entry point. Upcoming posts: Day Type Topic Day 1 Exercise Reading the Agent Loop in 120 lines Day 2 Core Constraints and interception: hooks and permissions Day 3 Exercise Adding an approval gate with hooks Day 4 Core Extensions vs plugins: Pi vs DSH Day 5 Exercise Writing a Pi extension Day 6 Exercise Composing DSH Cordis plugin modes Day 7 Core Agent Teams and task DAGs Day 8 Core Memory and learning: Hermes, Nowledge Mem, EvoMap Day 9 Exercise Designing your own skill system Day 10 Wrap-up L3 graduation check Start by Remembering Your Day 4 Script Think back to Day 4 of L2. In that lesson we wrote a batch script: read files from a folder, call the API on each one, write the results back, and when a step failed, log the error first, then keep going. ...
2026-08-27 · 12 min · Alex Wang

omo vs oms: Fallback Chains Deep Dive

This is Part 2 of When Your AI Coding Tool Needs Three Configs. Part 1 covered the config design, file structure, and orchestration philosophy. This article focuses on fallback mechanisms. omo = oh-my-openagent, oms = oh-my-opencode-slim. Model and provider names are anonymized as provider-a/model-x etc. Why Bother Understanding Fallback omo and oms both support fallback: automatic switching to backup when the primary model is unavailable. But their mechanisms differ completely: omo is a multi-layer pipeline that degrades step by step; oms uses startup model selection + runtime abort retry. You need to understand this difference to configure a reliable chain. ...

2026-06-07 · 13 min · Alex Wang

When Your AI Coding Tool Needs Three Configs

Why I Need Three OpenCode Configs I have three opencode.json files in my ~/.config/opencode/ directory. The reason is simple: I wanted to run oh-my-openagent (omo from here on) and oh-my-opencode-slim (oms from here on) side by side, comparing them to understand where each one’s boundaries lie. omo is the full version—it comes with a batch of built-in agents (Sisyphus, Atlas, Prometheus, Oracle, Explore, Librarian, Metis, Momus, etc.), plus the ones I register on demand. The core is the fallback chain and the Sisyphus orchestrator: throw a refactoring task at Sisyphus, and it breaks the task down for Prometheus to plan, Atlas to execute the plan and distribute subtasks, Explore to search code, Oracle to analyze, then Sisyphus aggregates the results. oms is the slim version—it also has an orchestrator as the main agent responsible for executing tasks, but the difference is in the review phase: oms uses council multi-model consensus, where multiple councillors review results in parallel, and the Council agent synthesizes outputs from all councillors to reach a final conclusion. ...

2026-06-05 · 10 min · Alex Wang
A row of dim review dimension slots with only one glowing, then fully lit after new modules are added, but the version on the right, weighed down by math symbols, has gone dark again

Dimension Experiments: Can a 36-Year-Old Book Fix Your Review Coverage?

Series: Classic Theory Meets Agent Practice (Part 3) Part 1: Dual-Pass Review: Why You Can’t Have Both Recall and Precision · Part 2: Strategy Genes: Pruning Review Prompts with Genetic Algorithm Thinking TL;DR: Two controlled experiments. Code review dimensions went from 8 to 11, and known-issue detection went from 1/6 to 6/6. Design review introduced Axiomatic Design dimensions, and detection also went from 1/6 to 6/6. But the version with a math formula proved that more dimensions are not always better: computation consumed review attention, and findings dropped 35%. Run controlled experiments with known issues as reference, and you learn which dimensions actually work. ...

2026-05-25 · 9 min · Alex Wang
A bloated prompt pruned into compact strategy genes, with redundant fragments removed and core constraints preserved

Strategy Genes: Pruning Review Prompts with Genetic Algorithm Thinking

Series: Classic Theory Meets Agent Practice (Part 2) Previous: Dual-Pass Review: Why Recall and Precision Cannot Both Win Next: Dimension Experiments: Can a 36-Year-Old Book Fix Your Review Coverage? TL;DR: A review prompt went from 317 lines to 135 lines (-58%), and review quality improved by 29%. What I removed was not useful procedure, but redundant content the model could infer on its own. What stayed were strategy genes: irreplaceable constraints, negative examples, and tone locks. ...

2026-05-24 · 10 min · Alex Wang
Two funnels side by side: the left one wide-mouthed catching many candidate issues, the right one narrow filtering only the valuable findings

Cascade Retrieval: A 15-Year-Old IR Trick Fixed My Design Review Agent

Series: Classic Theory Meets Agent Practice (Part 1) TL;DR: A design review agent needs to find every issue AND avoid false positives. One agent can’t do both. Borrowing cascade retrieval from information retrieval, a 15-year-old method, I split it into two: a Recall Pass that casts a wide net, and a Precision Pass that filters strictly. Real defects get caught earlier, and the risk of rework during development drops. This series is about one thing: how classic theoretical frameworks directly guide AI agent engineering. The first post starts with cascade retrieval, a 15-year-old method from information retrieval (IR), and the much older Recall vs. Precision tradeoff it sits on top of. The 1966 Cranfield II experiments proved these two goals fight each other. Applying that old problem’s newer solution to design review made a striking difference. ...

2026-05-22 · 9 min · Alex Wang
Context rot: an easily overlooked problem in AI coding

Context Rot: An Easily Overlooked Problem in AI Coding

Yesterday someone in a group chat said GPT-5.4 performed worse than Doubao. When they asked questions, the model would often give irrelevant answers without even reading the question. I asked a few follow-up questions and found they had fed it a lot of documents, and the conversation had gone on for many turns. This probably wasn’t the model’s problem; it was context rot. I’ve had similar experiences myself. After talking to a model for a long time, it starts “forgetting” what we discussed earlier, or repeats mistakes that were already corrected. The model hasn’t gotten stupider. The conversation has just gotten too long. ...

2026-04-18 · 15 min · Alex Wang
Seven human-AI collaboration patterns from the Aristotle project

Looking Back: Seven Human-AI Collaboration Patterns in the Aristotle Project

Five articles in. Time to step back and look at the path itself. Aristotle: Teaching AI to Reflect on Its Mistakes covered the design philosophy and initial implementation. claude-code-reflect: Same Metacognition, Different Soil told the story of porting across platforms. Trust Boundaries: One Idea, Two Systems proposed a trust tiering model. From Scars to Armor: Harness Engineering in Practice validated the theory through refactoring. A Markdown’s Three Lives: From Static Rules to a Git-Backed MCP Server evolved the rule storage from append-only to the GEAR protocol. ...

2026-04-16 · 11 min · Alex Wang
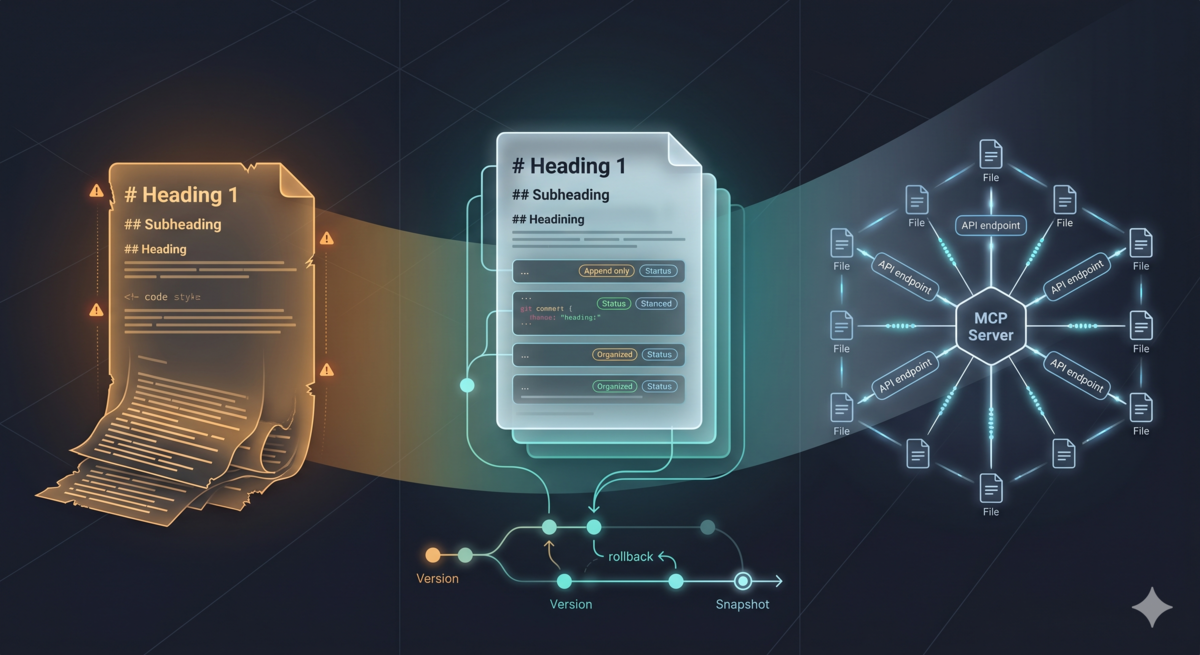
A Markdown's three lives: from static rules to Git-backed MCP Server

A Markdown's Three Lives: From Static Rules to Git-Backed MCP Server

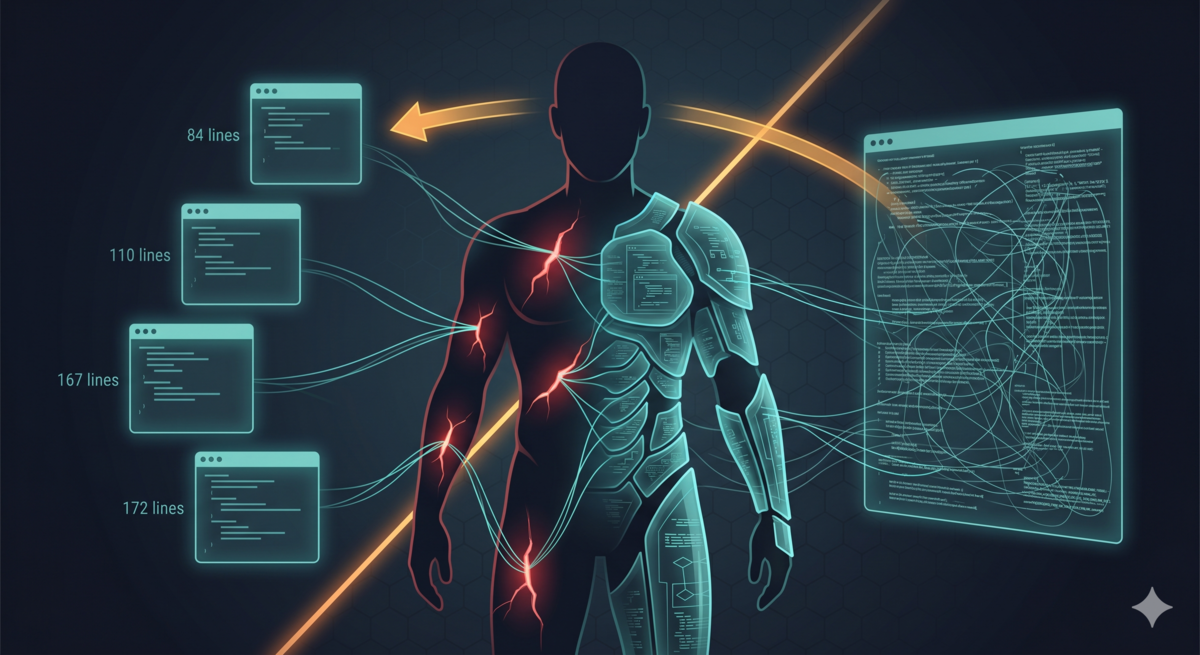
The previous article, From Scars to Armor: Harness Engineering in Practice, ended with Aristotle having a streamlined router (SKILL.md compressed from 371 lines to 84), an on-demand progressive disclosure architecture, and a working reflect→review→confirm workflow. But one thread never got pulled: Where do confirmed rules actually live? This article follows that thread. It wasn’t planned from the start. Three concrete problems in actual use forced the design out, step by step. ...

2026-04-16 · 20 min · Alex Wang
From scars to armor: Progressive Disclosure architecture reforged from four defects

From Scars to Armor: Harness Engineering in Practice

Three articles in. Back to code, and a hard look in the mirror. The first post, Aristotle: Teaching AI to Reflect on Its Mistakes, covered the design philosophy and a smooth implementation: three commits in one go. The second, claude-code-reflect: Same Metacognition, Different Soil, described the adaptation cost of moving the same philosophy to Claude Code: continuous iteration from V1 to V3. The third, Trust Boundaries: The Same Idea on Open and Closed Platforms, proposed a tiered trust model and a harness engineering framework. ...

2026-04-11 · 14 min · Alex Wang